Liquid Inference Review (2026): LLM Router Where Providers Compete per Prompt
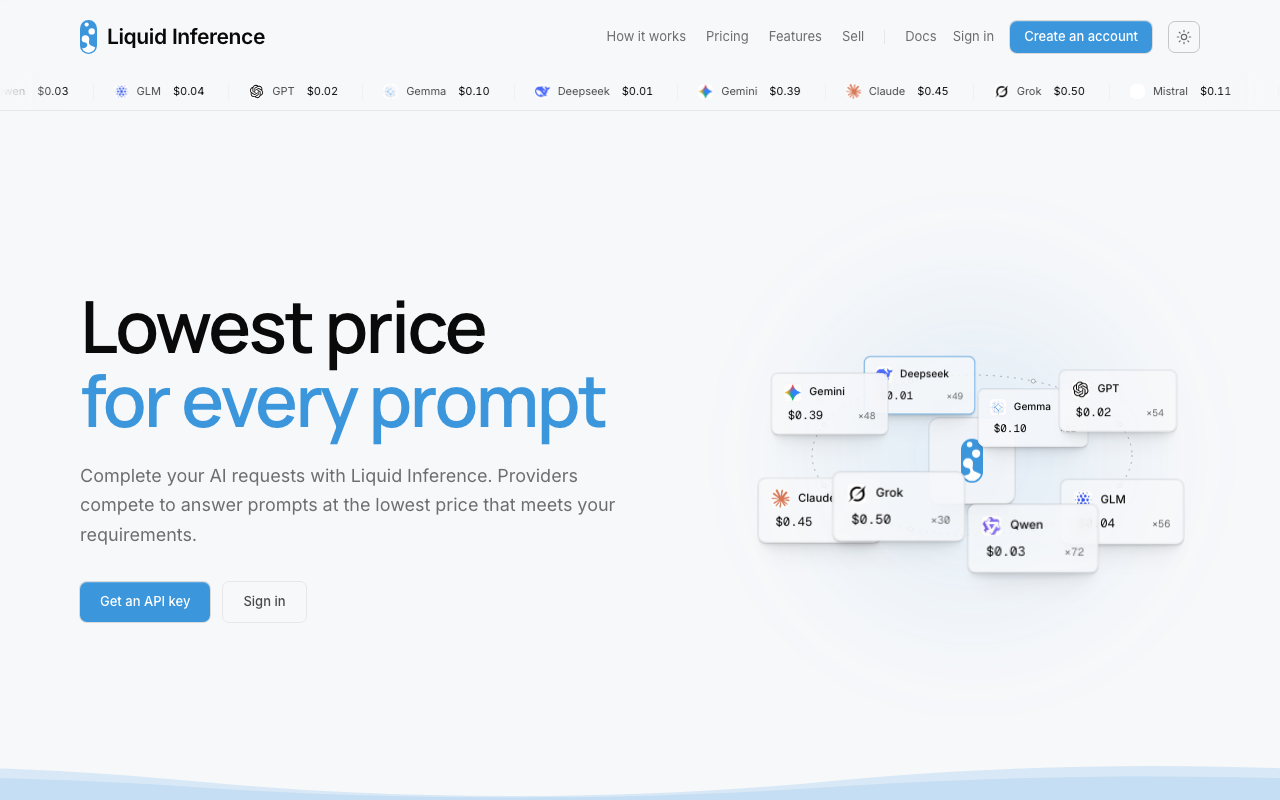
LLM router where model providers compete for every prompt, routing each request to the cheapest qualifying provider
Category: data · Pricing model: freemium (usage-based, unverified) · Official site: liquidinference.ai
What Liquid Inference does
Liquid Inference is an LLM router from Architect (the team behind ai.exchange): instead of pinning a single model provider, providers compete for every prompt you send, and the router sends each request to the cheapest provider that still meets your quality requirements. The pitch is “lowest price for every prompt” — you set a task, and the system auctions it across models in real time. It was launched on Product Hunt in October 2026.
Who it’s for
Engineering teams and product builders running high-volume LLM workloads (chat, RAG, agents) who care about per-token cost and want price competition across providers instead of a single-vendor contract. It is an infrastructure primitive, not a consumer chatbot.
Key features
- Per-prompt provider competition (dynamic routing per request)
- Price-optimized: routes to the cheapest qualifying provider
- Quality constraints so “cheap” does not mean “wrong”
- Built by Architect / ai.exchange
- Positioned as cost infrastructure for LLM-heavy apps
How to use Liquid Inference
- Create an account at liquidinference.ai.
- Connect your application through the router (API key / SDK).
- Set quality or model constraints per task.
- Send prompts; the router picks the cheapest qualifying provider per request.
- Monitor routing decisions and spend (details in the product docs).
Limitations
- The site is client-side rendered; at check time no static pricing page or rate card was reachable, so plan and per-token pricing are unverified.
- Young (October 2026) launch — the provider pool, routing policy, and guarantees are still thin.
- “Cheapest qualifying” depends on how well your quality constraints are specified; mis-specification can mean wrong output or higher cost.
- Adds a routing layer between you and model providers (another dependency and a data path).
- Specific SLAs, data handling, and compliance terms were not visible at check time.
Pricing
Could not be verified on 2026-10-09: liquidinference.ai renders its content client-side and no pricing page or rate card was reachable at check time. The model is usage-based per prompt (providers compete on price). Confirm current rates and any platform fee in the product’s docs before relying on this listing.
Best for
Teams running LLM-heavy workloads who want to turn provider pricing into a per-prompt auction and cut token spend without a single-vendor lock-in.
Alternatives
- Zapier — automation glue across SaaS, a different layer (not model routing).
- Perplexity — a finished LLM product, not routing infrastructure.
- Gemini Notebook — a single-provider AI assistant, the opposite of multi-provider routing.
No comments yet. Be the first to share.