What is headroom?
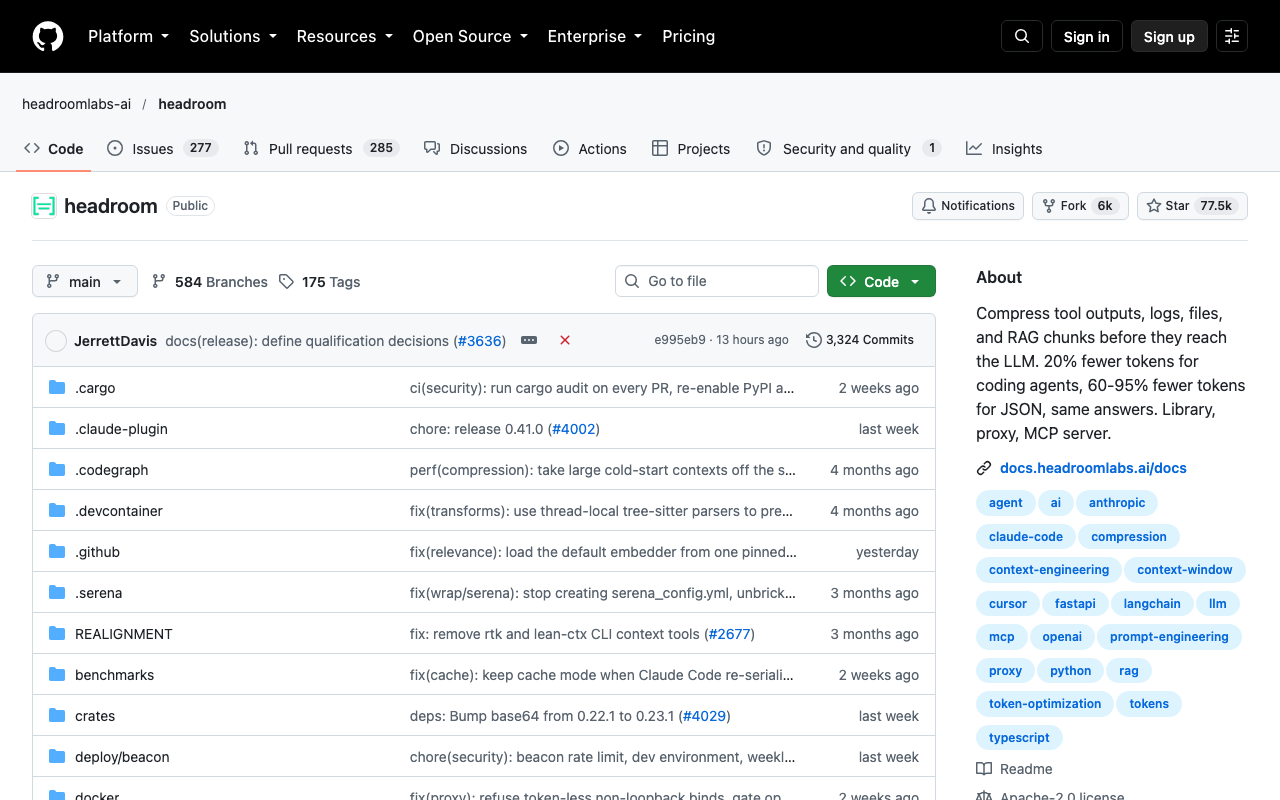
headroom is a tool designed to compress various data types, including tool outputs, logs, files, and Retrieval-Augmented Generation (RAG) chunks, before they are processed by Large Language Models. It aims to significantly reduce token consumption, claiming up to 20% fewer tokens for coding agents and 60-95% fewer tokens for other data types. The project is available as an open-source repository on GitHub.
Key Features
- Context Compression: Compresses tool outputs, logs, files, and RAG chunks before they reach the LLM.
- Token Reduction: Claims to reduce token usage by 20% for coding agents and 60-95% for other data types.
- Open Source: Available as a public repository on GitHub for developers to inspect and use.
Pricing
Public / open project materials as listed on the official site or repository; confirm license and any paid packaging there before relying on this page.
Limitations
- Performance Claims: The stated token reduction percentages (20% for coding, 60-95% for others) are based on the project’s claims and may vary depending on the specific data and LLM used.
- Open Source Status: As an open-source project, it may lack the dedicated support, SLAs, and enterprise-grade features typically found in commercial SaaS products.
Who is it for?
Developers and AI engineers looking to optimize token usage and reduce costs when working with Large Language Models, particularly in scenarios involving large volumes of logs, files, or RAG data.
Alternatives
- HOL Guard — Policy checks for coding-agent actions
- OpenCode — Open-source coding agent across surfaces
- Antigravity CLI — Terminal coding agent with MCP
No comments yet. Be the first to share.